

Excellent Professional-Machine-Learning-Engineer PDF Dumps With 100% TorrentVCE Exam Passing Guaranted [Nov-2021]
100% Pass Your Professional-Machine-Learning-Engineer Google Professional Machine Learning Engineer at First Attempt with TorrentVCE
What is the duration, language, and format of Professional Machine Learning Engineer - Google
- Language of Exam: English, Japanese, Korean
- Duration of Exam: 120 minutes
- No negative marking for wrong answers
- Type of Questions: Multiple choice (MCQs), multiple answers
Professional Machine Learning Engineer - Google Certification Path
The associate level certification is focused on the fundamental skills of deploying, monitoring, and maintaining projects on Google Cloud. This certification is a good starting point for those new to cloud and can be used as a path to professional level certifications.
Professional certifications span key technical job functions and assess advanced skills in design, implementation, and management. These certifications are recommended for individuals with industry experience and familiarity with Google Cloud products and solutions.
NEW QUESTION 20
You are building a linear regression model on BigQuery ML to predict a customer's likelihood of purchasing your company's products. Your model uses a city name variable as a key predictive component. In order to train and serve the model, your data must be organized in columns. You want to prepare your data using the least amount of coding while maintaining the predictable variables. What should you do?
- A. Use Dataprep to transform the state column using a one-hot encoding method, and make each city a column with binary values.
- B. Use TensorFlow to create a categorical variable with a vocabulary list Create the vocabulary file, and upload it as part of your model to BigQuery ML.
- C. Create a new view with BigQuery that does not include a column with city information
- D. Use Cloud Data Fusion to assign each city to a region labeled as 1, 2, 3, 4, or 5r and then use that number to represent the city in the model.
Answer: D
NEW QUESTION 21
Your organization's call center has asked you to develop a model that analyzes customer sentiments in each call. The call center receives over one million calls daily, and data is stored in Cloud Storage. The data collected must not leave the region in which the call originated, and no Personally Identifiable Information (Pll) can be stored or analyzed. The data science team has a third-party tool for visualization and access which requires a SQL ANSI-2011 compliant interface. You need to select components for data processing and for analytics. How should the data pipeline be designed?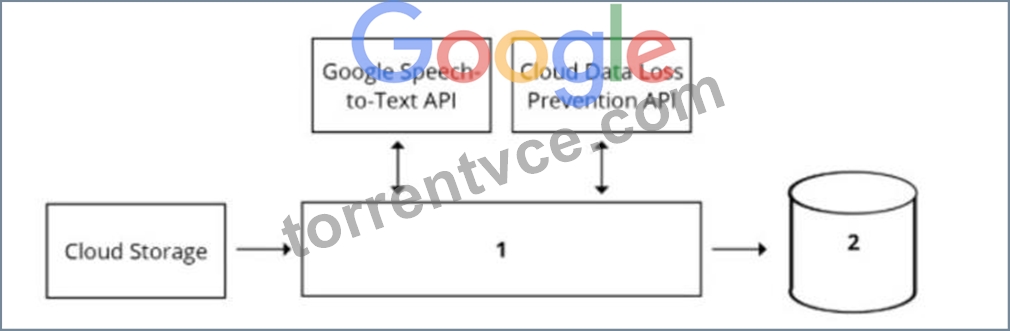
- A. 1 = Cloud Function, 2 = Cloud SQL
- B. 1 = Dataflow, 2 = BigQuery
- C. 1 = Pub/Sub, 2 = Datastore
- D. 1 = Dataflow, 2 = Cloud SQL
Answer: C
NEW QUESTION 22
You have been asked to develop an input pipeline for an ML training model that processes images from disparate sources at a low latency. You discover that your input data does not fit in memory. How should you create a dataset following Google-recommended best practices?
- A. Create a tf.data.Dataset.prefetch transformation
- B. Convert the images to tf .Tensor Objects, and then run Dataset. from_tensor_slices{).
- C. Convert the images to tf .Tensor Objects, and then run tf. data. Dataset. from_tensors ().
- D. Convert the images Into TFRecords, store the images in Cloud Storage, and then use the tf. data API to read the images for training
Answer: D
NEW QUESTION 23
A Machine Learning Specialist is required to build a supervised image-recognition model to identify a cat. The ML Specialist performs some tests and records the following results for a neural network-based image classifier:
Total number of images available = 1,000
Test set images = 100 (constant test set)
The ML Specialist notices that, in over 75% of the misclassified images, the cats were held upside down by their owners.
Which techniques can be used by the ML Specialist to improve this specific test error?
- A. Increase the training data by adding variation in rotation for training images.
- B. Increase the number of layers for the neural network.
- C. Increase the number of epochs for model training
- D. Increase the dropout rate for the second-to-last layer.
Answer: C
NEW QUESTION 24
You are developing models to classify customer support emails. You created models with TensorFlow Estimators using small datasets on your on-premises system, but you now need to train the models using large datasets to ensure high performance. You will port your models to Google Cloud and want to minimize code refactoring and infrastructure overhead for easier migration from on-prem to cloud. What should you do?
- A. Create a cluster on Dataproc for training
- B. Use Al Platform for distributed training
- C. Use Kubeflow Pipelines to train on a Google Kubernetes Engine cluster.
- D. Create a Managed Instance Group with autoscaling
Answer: C
NEW QUESTION 25
A company is using Amazon Polly to translate plaintext documents to speech for automated company announcements. However, company acronyms are being mispronounced in the current documents.
How should a Machine Learning Specialist address this issue for future documents?
- A. Convert current documents to SSML with pronunciation tags.
- B. Create an appropriate pronunciation lexicon.
- C. Output speech marks to guide in pronunciation.
- D. Use Amazon Lex to preprocess the text files for pronunciation
Answer: A
Explanation:
Explanation/Reference: https://docs.aws.amazon.com/polly/latest/dg/ssml.html
NEW QUESTION 26
You need to design a customized deep neural network in Keras that will predict customer purchases based on their purchase history. You want to explore model performance using multiple model architectures, store training data, and be able to compare the evaluation metrics in the same dashboard. What should you do?
- A. Automate multiple training runs using Cloud Composer
- B. Create multiple models using AutoML Tables
- C. Create an experiment in Kubeflow Pipelines to organize multiple runs
- D. Run multiple training jobs on Al Platform with similar job names
Answer: D
NEW QUESTION 27
A large mobile network operating company is building a machine learning model to predict customers who are likely to unsubscribe from the service. The company plans to offer an incentive for these customers as the cost of churn is far greater than the cost of the incentive.
The model produces the following confusion matrix after evaluating on a test dataset of 100 customers:
Based on the model evaluation results, why is this a viable model for production?
- A. The model is 86% accurate and the cost incurred by the company as a result of false positives is less than the false negatives.
- B. The model is 86% accurate and the cost incurred by the company as a result of false negatives is less than the false positives.
- C. The precision of the model is 86%, which is greater than the accuracy of the model.
- D. The precision of the model is 86%, which is less than the accuracy of the model.
Answer: B
NEW QUESTION 28
You work on a growing team of more than 50 data scientists who all use Al Platform. You are designing a strategy to organize your jobs, models, and versions in a clean and scalable way. Which strategy should you choose?
- A. Use labels to organize resources into descriptive categories. Apply a label to each created resource so that users can filter the results by label when viewing or monitoring the resources
- B. Set up a BigQuery sink for Cloud Logging logs that is appropriately filtered to capture information about Al Platform resource usage In BigQuery create a SQL view that maps users to the resources they are using.
- C. Separate each data scientist's work into a different project to ensure that the jobs, models, and versions created by each data scientist are accessible only to that user.
- D. Set up restrictive I AM permissions on the Al Platform notebooks so that only a single user or group can access a given instance.
Answer: C
NEW QUESTION 29
You manage a team of data scientists who use a cloud-based backend system to submit training jobs. This system has become very difficult to administer, and you want to use a managed service instead. The data scientists you work with use many different frameworks, including Keras, PyTorch, theano. Scikit-team, and custom libraries. What should you do?
- A. Set up Slurm workload manager to receive jobs that can be scheduled to run on your cloud infrastructure.
- B. Configure Kubeflow to run on Google Kubernetes Engine and receive training jobs through TFJob
- C. Use the Al Platform custom containers feature to receive training jobs using any framework
- D. Create a library of VM images on Compute Engine; and publish these images on a centralized repository
Answer: A
NEW QUESTION 30
You are training an LSTM-based model on Al Platform to summarize text using the following job submission script: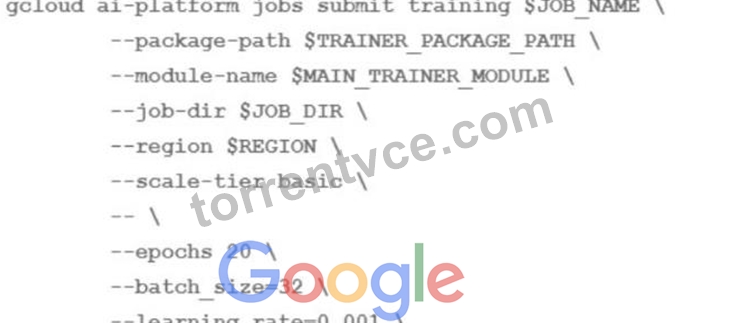
You want to ensure that training time is minimized without significantly compromising the accuracy of your model. What should you do?
- A. Modify the batch size' parameter
- B. Modify the 'epochs' parameter
- C. Modify the 'scale-tier' parameter
- D. Modify the 'learning rate' parameter
Answer: A
NEW QUESTION 31
A Machine Learning Specialist has completed a proof of concept for a company using a small data sample, and now the Specialist is ready to implement an end-to-end solution in AWS using Amazon SageMaker. The historical training data is stored in Amazon RDS.
Which approach should the Specialist use for training a model using that data?
- A. Move the data to Amazon DynamoDB and set up a connection to DynamoDB within the notebook to pull data in.
- B. Write a direct connection to the SQL database within the notebook and pull data in
- C. Push the data from Microsoft SQL Server to Amazon S3 using an AWS Data Pipeline and provide the S3 location within the notebook.
- D. Move the data to Amazon ElastiCache using AWS DMS and set up a connection within the notebook to pull data in for fast access.
Answer: C
NEW QUESTION 32
You have a functioning end-to-end ML pipeline that involves tuning the hyperparameters of your ML model using Al Platform, and then using the best-tuned parameters for training. Hypertuning is taking longer than expected and is delaying the downstream processes. You want to speed up the tuning job without significantly compromising its effectiveness. Which actions should you take?
Choose 2 answers
- A. Decrease the maximum number of trials during subsequent training phases.
- B. Set the early stopping parameter to TRUE
- C. Decrease the range of floating-point values
- D. Decrease the number of parallel trials
- E. Change the search algorithm from Bayesian search to random search.
Answer: A,E
NEW QUESTION 33
You work for a social media company. You need to detect whether posted images contain cars. Each training example is a member of exactly one class. You have trained an object detection neural network and deployed the model version to Al Platform Prediction for evaluation. Before deployment, you created an evaluation job and attached it to the Al Platform Prediction model version. You notice that the precision is lower than your business requirements allow. How should you adjust the model's final layer softmax threshold to increase precision?
- A. Decrease the recall.
- B. Decrease the number of false negatives
- C. Increase the number of false positives
- D. Increase the recall
Answer: B
NEW QUESTION 34
A trucking company is collecting live image data from its fleet of trucks across the globe. The data is growing rapidly and approximately 100 GB of new data is generated every day. The company wants to explore machine learning uses cases while ensuring the data is only accessible to specific IAM users.
Which storage option provides the most processing flexibility and will allow access control with IAM?
- A. Use a database, such as Amazon DynamoDB, to store the images, and set the IAM policies to restrict access to only the desired IAM users.
- B. Use an Amazon S3-backed data lake to store the raw images, and set up the permissions using bucket policies.
- C. Configure Amazon EFS with IAM policies to make the data available to Amazon EC2 instances owned by the IAM users.
- D. Setup up Amazon EMR with Hadoop Distributed File System (HDFS) to store the files, and restrict access to the EMR instances using IAM policies.
Answer: D
Explanation:
Explanation
NEW QUESTION 35
You are designing an ML recommendation model for shoppers on your company's ecommerce website. You will use Recommendations Al to build, test, and deploy your system. How should you develop recommendations that increase revenue while following best practices?
- A. Because it will take time to collect and record product data, use placeholder values for the product catalog to test the viability of the model.
- B. Use the "Frequently Bought Together' recommendation type to increase the shopping cart size for each order.
- C. Use the "Other Products You May Like" recommendation type to increase the click-through rate
- D. Import your user events and then your product catalog to make sure you have the highest quality event stream
Answer: B
Explanation:
Frequently bought together' recommendations aim to up-sell and cross-sell customers by providing product.
NEW QUESTION 36
A Mobile Network Operator is building an analytics platform to analyze and optimize a company's operations using Amazon Athena and Amazon S3.
The source systems send data in .CSV format in real time. The Data Engineering team wants to transform the data to the Apache Parquet format before storing it on Amazon S3.
Which solution takes the LEAST effort to implement?
- A. Ingest .CSV data using Apache Kafka Streams on Amazon EC2 instances and use Kafka Connect S3 to serialize data as Parquet
- B. Ingest .CSV data from Amazon Kinesis Data Streams and use Amazon Glue to convert data into Parquet.
- C. Ingest .CSV data using Apache Spark Structured Streaming in an Amazon EMR cluster and use Apache Spark to convert data into Parquet.
- D. Ingest .CSV data from Amazon Kinesis Data Streams and use Amazon Kinesis Data Firehose to convert data into Parquet.
Answer: B
Explanation:
Explanation/Reference:
NEW QUESTION 37
You work for a toy manufacturer that has been experiencing a large increase in demand. You need to build an ML model to reduce the amount of time spent by quality control inspectors checking for product defects. Faster defect detection is a priority. The factory does not have reliable Wi-Fi. Your company wants to implement the new ML model as soon as possible. Which model should you use?
- A. AutoML Vision Edge mobile-versatile-1 model
- B. AutoML Vision Edge mobile-low-latency-1 model
- C. AutoML Vision model
- D. AutoML Vision Edge mobile-high-accuracy-1 model
Answer: C
NEW QUESTION 38
A Machine Learning team runs its own training algorithm on Amazon SageMaker. The training algorithm requires external assets. The team needs to submit both its own algorithm code and algorithm-specific parameters to Amazon SageMaker.
What combination of services should the team use to build a custom algorithm in Amazon SageMaker?
(Choose two.)
- A. AWS CodeStar
- B. Amazon ECR
- C. AWS Secrets Manager
- D. Amazon S3
- E. Amazon ECS
Answer: B,D
NEW QUESTION 39
A Machine Learning Specialist is building a model that will perform time series forecasting using Amazon SageMaker. The Specialist has finished training the model and is now planning to perform load testing on the endpoint so they can configure Auto Scaling for the model variant.
Which approach will allow the Specialist to review the latency, memory utilization, and CPU utilization during the load test?
- A. Generate an Amazon CloudWatch dashboard to create a single view for the latency, memory utilization, and CPU utilization metrics that are outputted by Amazon SageMaker.
- B. Send Amazon CloudWatch Logs that were generated by Amazon SageMaker to Amazon ES and use Kibana to query and visualize the log data.
- C. Build custom Amazon CloudWatch Logs and then leverage Amazon ES and Kibana to query and visualize the log data as it is generated by Amazon SageMaker.
- D. Review SageMaker logs that have been written to Amazon S3 by leveraging Amazon Athena and Amazon QuickSight to visualize logs as they are being produced.
Answer: A
Explanation:
Explanation/Reference: https://docs.aws.amazon.com/sagemaker/latest/dg/monitoring-cloudwatch.html
NEW QUESTION 40
You are an ML engineer at a bank that has a mobile application. Management has asked you to build an ML-based biometric authentication for the app that verifies a customer's identity based on their fingerprint. Fingerprints are considered highly sensitive personal information and cannot be downloaded and stored into the bank databases. Which learning strategy should you recommend to train and deploy this ML model?
- A. Federated learning
- B. Data Loss Prevention API
- C. MD5 to encrypt data
- D. Differential privacy
Answer: A
NEW QUESTION 41
A Machine Learning Specialist is working with a large company to leverage machine learning within its products. The company wants to group its customers into categories based on which customers will and will not churn within the next 6 months. The company has labeled the data available to the Specialist.
Which machine learning model type should the Specialist use to accomplish this task?
- A. Clustering
- B. Classification
- C. Reinforcement learning
- D. Linear regression
Answer: B
Explanation:
The goal of classification is to determine to which class or category a data point (customer in our case) belongs to. For classification problems, data scientists would use historical data with predefined target variables AKA labels (churner/non-churner) - answers that need to be predicted - to train an algorithm. With classification, businesses can answer the following questions:
* Will this customer churn or not?
* Will a customer renew their subscription?
* Will a user downgrade a pricing plan?
* Are there any signs of unusual customer behavior?
Reference: https://www.kdnuggets.com/2019/05/churn-prediction-machine-learning.html
NEW QUESTION 42
......
How to Prepare For Professional Machine Learning Engineer - Google
Preparation Guide for Professional Machine Learning Engineer - Google
Introduction for Professional Machine Learning Engineer - Google
A Professional Machine Learning Engineer designs, builds, and productionizes ML models to solve business challenges using Google Cloud technologies and knowledge of proven ML models and techniques. The ML Engineer is proficient in all aspects of model architecture, data pipeline interaction, and metrics interpretation and needs familiarity with application development, infrastructure management, data engineering, and security.
The Professional Machine Learning Engineer exam assesses your ability to:
- Architect ML solutions
- Prepare and process data
- Develop ML models
- Automate & orchestrate ML pipelines
- Monitor, optimize, and maintain ML solutions
- Frame ML problems
We prepare Google Professional-Machine-Learning-Engineer practice exams and Google Professional-Machine-Learning-Engineer practice tests to prepare you for all these requirements.
Trend for Professional-Machine-Learning-Engineer pdf dumps before actual exam: https://www.torrentvce.com/Professional-Machine-Learning-Engineer-valid-vce-collection.html
Real Exam Questions & Answers - Google Professional-Machine-Learning-Engineer Dump is Ready: https://drive.google.com/open?id=1hWpuKztpd4lKjR_cuWkIsKstSaYSdzKa